Inside xAI Colossus: The 100,000-GPU NVIDIA H100 Cluster
With special access from Elon Musk and the xAI team, Patrick Kennedy of ServeTheHome (STH) recently toured the interior of Colossus, xAI’s massive AI training cluster. The resulting photos and video provide an unusually detailed view of the infrastructure behind one of the world’s largest GPU deployments.
Colossus is not simply a collection of GPU servers. At this scale, the architecture becomes a systems-engineering problem spanning GPU compute, liquid cooling, power delivery, storage, networking, and cluster management.
This article examines the major building blocks visible inside the Colossus data center and how they work together to support large-scale AI training.
🔮 NVIDIA HGX: The Compute Foundation #
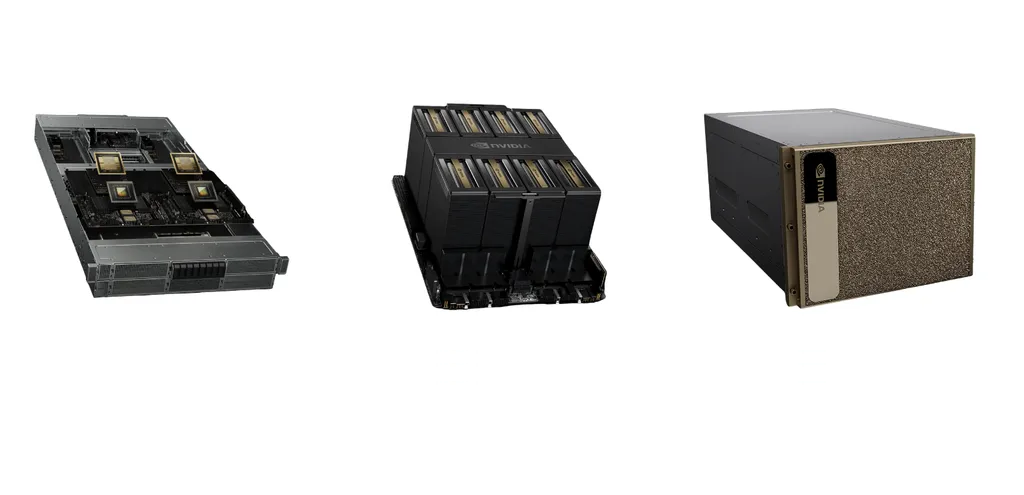
At the core of Colossus are Supermicro 4U liquid-cooled servers based on the NVIDIA HGX H100 platform.
HGX, MGX, and DGX #
NVIDIA uses several platform models for building AI systems, but they serve different purposes:
- MGX — A modular platform designed for OEM and system-builder configurations.
- HGX — A high-density GPU platform commonly used by hyperscalers and server manufacturers such as Supermicro.
- DGX — NVIDIA’s fully integrated, NVIDIA-branded AI system.
Colossus is a hyperscale deployment, so xAI uses HGX-based systems rather than NVIDIA’s complete DGX appliances.
Rack Layout and Cluster Scale #
Each 4U server contains eight NVIDIA H100 GPUs.
The deployment can be viewed hierarchically:
- 1 server → 8 H100 GPUs
- 1 rack → 8 servers → 64 H100 GPUs
- 1 pod → 8 racks → 512 H100 GPUs
- ~200 pods → approximately 100,000 H100 GPUs
This illustrates an important characteristic of modern AI infrastructure: once GPU counts reach this scale, the data center itself effectively becomes part of the computer.
The Supermicro systems used at Colossus are purpose-built for direct liquid cooling, rather than being conventional air-cooled servers retrofitted with liquid-cooling hardware. Internal components are mounted on removable trays, simplifying service operations without requiring the entire chassis to be removed from the rack.
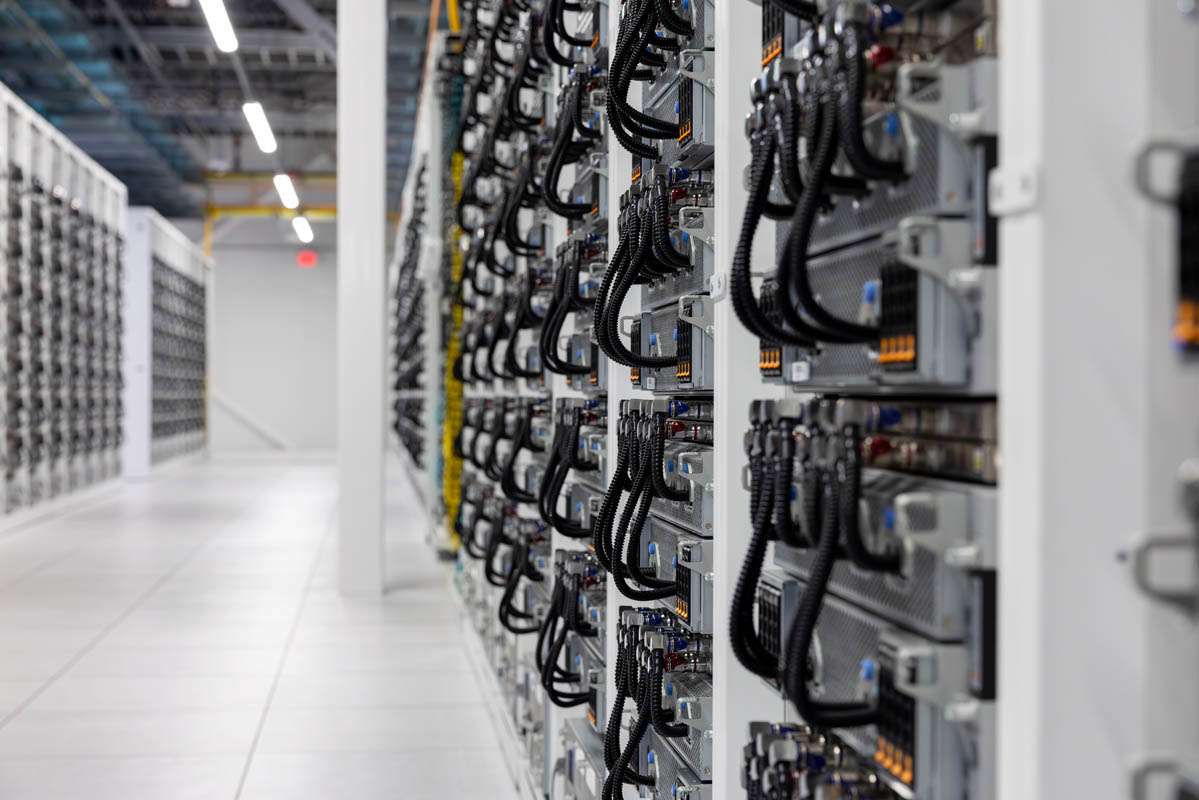
At the rear of each server, the infrastructure includes:
- Four redundant power supplies
- Three-phase power distribution
- Multiple 400GbE network connections
- A 1U coolant manifold
- Connections to a bottom-mounted Cooling Distribution Unit (CDU)
- Redundant coolant pumps
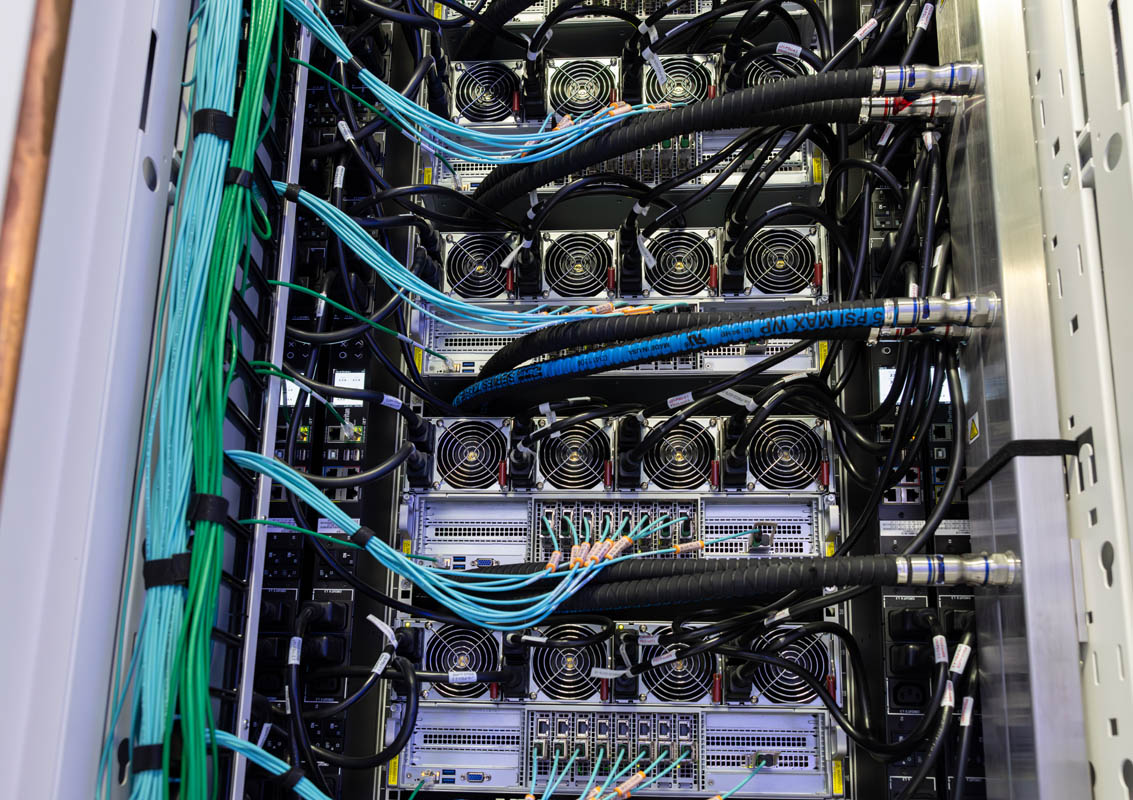
Liquid cooling is critical at this density because removing heat from hundreds or thousands of high-power GPUs becomes impractical with traditional air cooling alone.
💧 Direct Liquid Cooling at Rack Scale #
The thermal design is one of the most important aspects of Colossus.
An H100-based server can generate substantial heat under sustained AI training workloads. At cluster scale, the challenge is no longer simply keeping individual GPUs within their operating temperature range; the facility must continuously transport and reject enormous amounts of heat.
Colossus therefore integrates liquid cooling directly into the server and rack infrastructure.
The general cooling path is:
GPU → cold plate → coolant loop → manifold → CDU → facility cooling system
The CDU separates the server-side coolant loop from the facility-side cooling infrastructure while providing controlled heat exchange and redundant pumping.
This approach enables much higher compute density than traditional air-cooled racks and reduces the amount of airflow infrastructure required around the servers.
💾 High-Density NVMe Storage #
Compute is only one part of an AI training cluster. Large-scale training also requires a storage subsystem capable of feeding data to thousands of GPUs without becoming a bottleneck.
Colossus uses Supermicro NVMe storage systems with dense 2.5-inch NVMe SSD configurations. This reflects a broader industry trend toward high-performance all-flash storage in large AI clusters.
At hyperscale, all-flash storage can provide several advantages:
- Higher I/O performance
- Lower latency
- Higher storage density
- Improved power efficiency per unit of performance
- Better operational efficiency at large scale
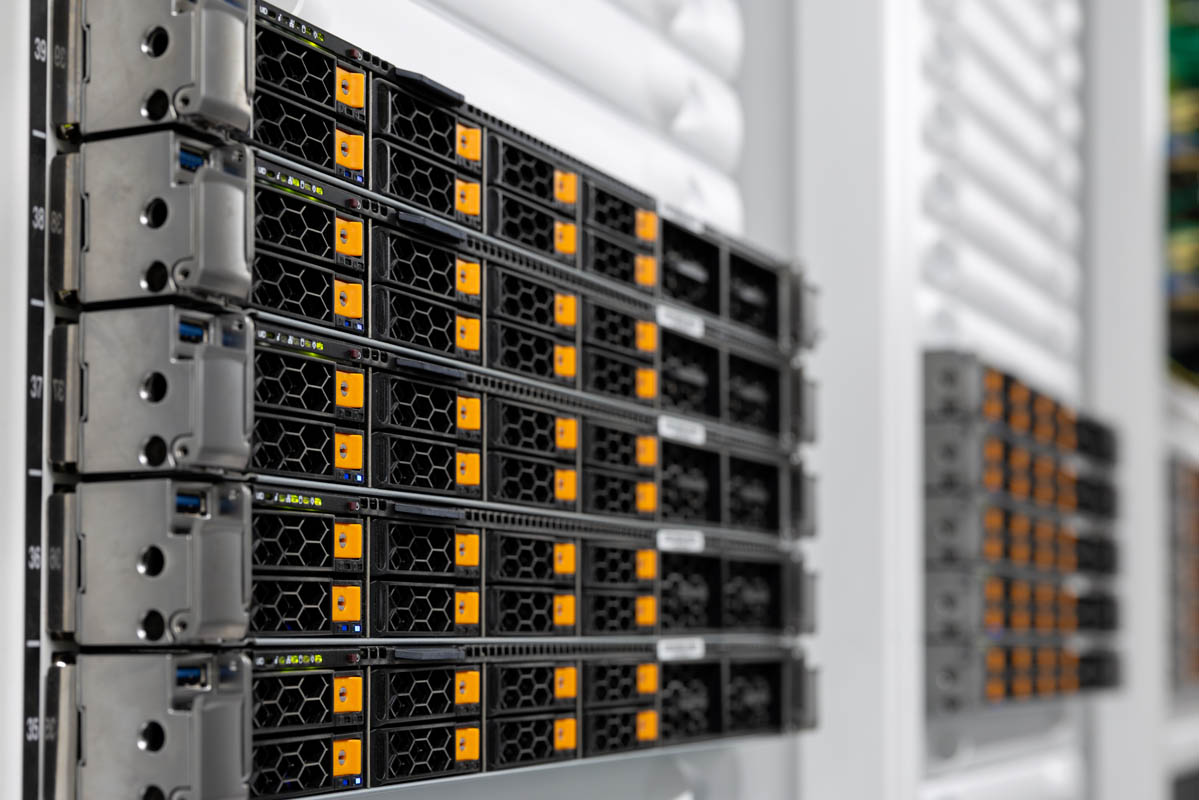
The raw cost per petabyte can be higher than lower-performance storage technologies, but at AI-cluster scale, the relevant metric is not simply $/TB. Storage performance, power consumption, rack density, and total cost of ownership all become part of the equation.
🌐 Spectrum-X Ethernet Instead of InfiniBand #
One of the most interesting architectural choices in Colossus is its use of NVIDIA Spectrum-X Ethernet for GPU-scale networking.
Many large AI supercomputers have traditionally relied on InfiniBand for high-performance GPU communication. xAI instead adopted an Ethernet-based architecture designed to provide the bandwidth, latency, congestion management, and RDMA capabilities required by distributed AI training.
The key advantages of this approach include:
- High aggregate bandwidth
- Low latency
- RDMA support
- Advanced congestion control
- Large-scale Ethernet interoperability
- Potentially lower deployment and operational complexity
Network Architecture #
The network infrastructure includes NVIDIA Spectrum switches and high-speed network adapters, including 400GbE NVIDIA BlueField-3 SuperNICs.
The server-level configuration includes:
- Spectrum SN5600 switches supporting high-speed Ethernet connectivity
- 400GbE BlueField-3 SuperNIC connectivity for GPU traffic
- Additional 400GbE networking for CPU-side traffic
- Approximately 3.6 Tbps of aggregate network bandwidth per server
Rather than placing every workload on a single fabric, xAI separates traffic into multiple logical networks:
- GPU network — High-priority RDMA traffic for distributed GPU communication
- CPU network — General compute, control, and management traffic
- Storage network — High-throughput access to NVMe storage
This separation prevents storage and management traffic from competing directly with latency-sensitive GPU-to-GPU communication.
Why 400GbE Matters #
At 400GbE, a single network link provides bandwidth that exceeds the aggregate PCIe bandwidth of many high-end CPU platforms from only a few generations ago.
More importantly, Colossus deploys multiple such links per server. The result is a networking subsystem whose aggregate bandwidth is measured in terabits per second, not gigabits.
For distributed training, this matters because GPUs constantly exchange activations, gradients, parameters, and synchronization data. At tens of thousands of GPUs, even small amounts of network inefficiency can translate into substantial compute underutilization.
NVIDIA reported that during Grok training, the Colossus network achieved:
- 0% packet loss
- Approximately 95% sustained throughput under heavy load
NVIDIA contrasted this with roughly 60% utilization for more conventional Ethernet configurations under comparable conditions.
The important point is not simply the raw bandwidth. At this scale, predictable latency, congestion control, RDMA efficiency, and sustained utilization are equally important.
⚡ Tesla Megapacks for Power Stability #
The compute infrastructure is only as reliable as the electrical infrastructure supporting it.
Outside the Colossus facility, rows of Tesla Megapack battery systems provide additional power-buffering capacity.
Large AI clusters can create rapid changes in electrical demand as thousands of GPUs transition between different phases of computation. These changes can occur much faster than conventional grid infrastructure or backup generators can comfortably respond.
Battery energy storage can therefore act as a fast-response buffer:
Grid / generation → Megapack buffer → data center power infrastructure → GPU cluster
The batteries can help absorb short-duration fluctuations and provide additional stability during transient events.
At this scale, power management is not merely a facility concern. It is part of the compute architecture itself.
🏗️ Colossus as a Complete AI System #
The most important lesson from Colossus is that a modern AI supercomputer cannot be evaluated by GPU count alone.
The architecture is a tightly integrated system:
- NVIDIA H100 GPUs provide the compute.
- Supermicro HGX servers package the GPU infrastructure.
- Direct liquid cooling removes the enormous thermal load.
- NVMe flash storage supplies high-performance data access.
- Spectrum-X Ethernet connects GPUs and other cluster components at extreme bandwidth.
- BlueField-3 SuperNICs provide RDMA-capable networking.
- Separate network fabrics isolate GPU, CPU, and storage traffic.
- Tesla Megapacks provide fast electrical buffering for the facility.
At approximately 100,000 GPUs, every subsystem becomes a first-class component of the computer. A small inefficiency in networking, cooling, storage, or power delivery can be multiplied across the entire cluster.
That is what makes Colossus particularly interesting from a systems-engineering perspective: it demonstrates how AI infrastructure is evolving from individual GPU servers into fully integrated, data-center-scale computers.